Blog
Local AI
Running a language model on your own hardware: the GPU, the agent, and the working method.
-
A Home Assistant dashboard that writes its own welcome
Nine dashboard tabs became one page with a jump menu, badges that only appear when something needs attention, and a short welcome text written by a language model on my…
-
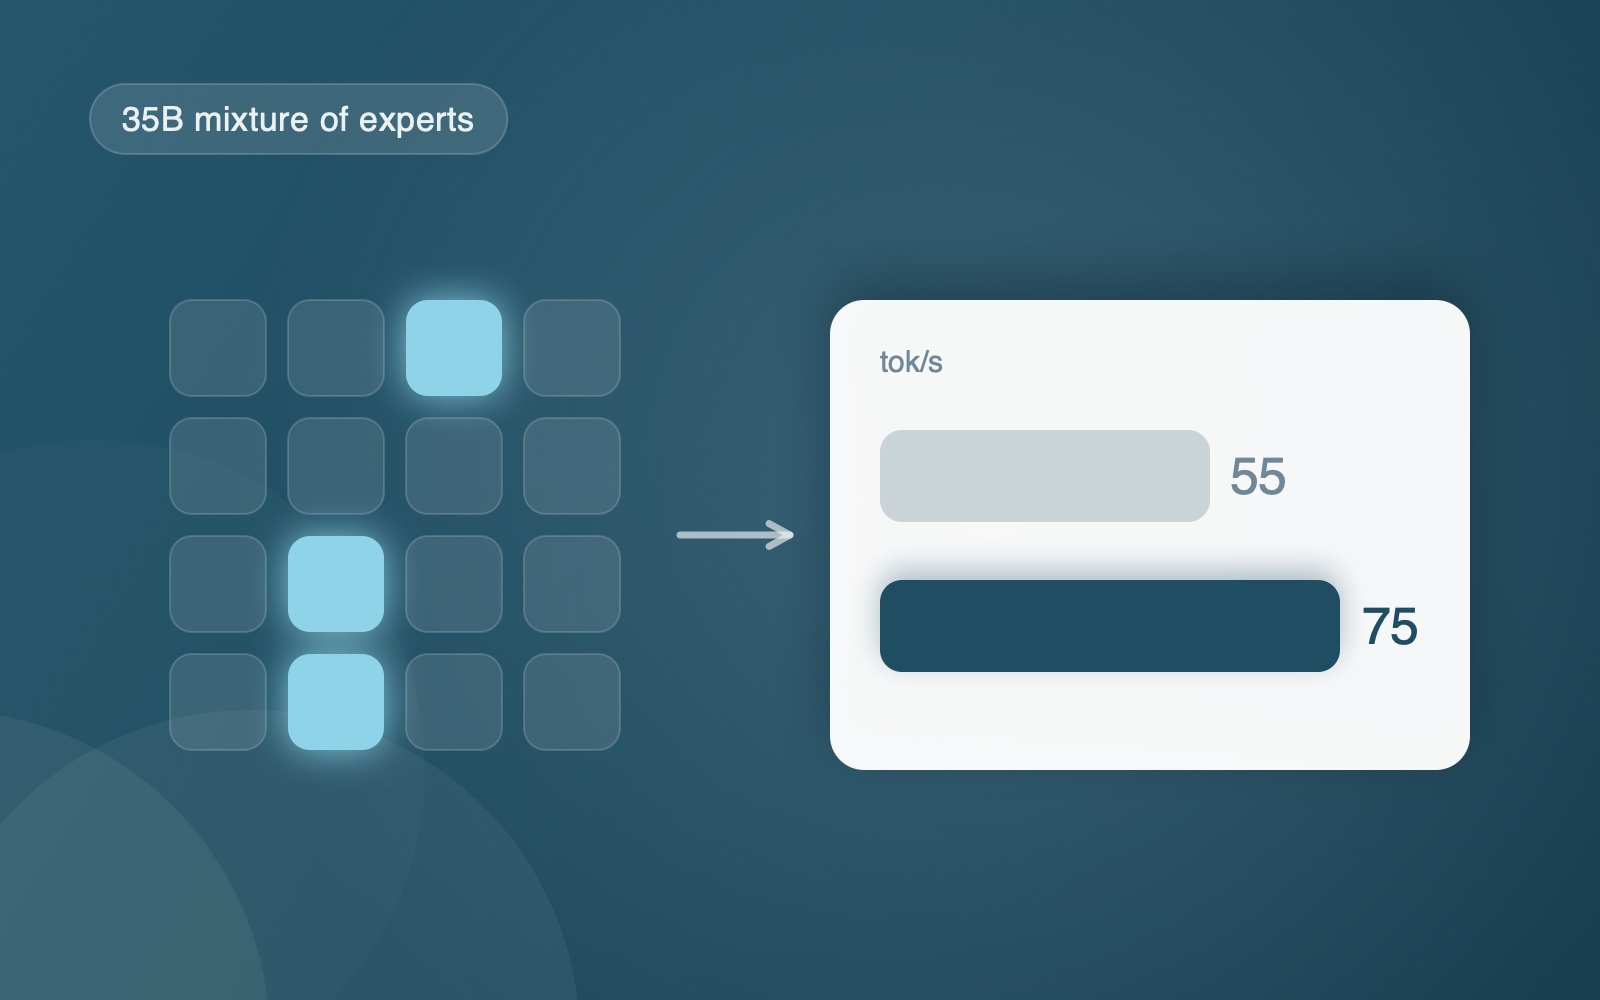
A 35B mixture-of-experts on the same Arc Pro B70
The rule I ended the first article with turned out to be about vLLM, not about the card. Swapping the runtime made a much larger model run faster.
-
Setting up Hermes on your own hardware
From GPU to working agent: three services, a proxy, and a handful of integrations.
-
Why an agent needs a working method
How 900 words of system prompt did more than a model twice the size.
-
An Intel Arc Pro B70 as a local LLM server
Why I chose Intel over NVIDIA, what it cost me in evenings, and why I would do it again.